Kategorien durchsuchen
Deutsch
$
USD
Deine KI mit Fiverr verbinden
Programmer Analyst
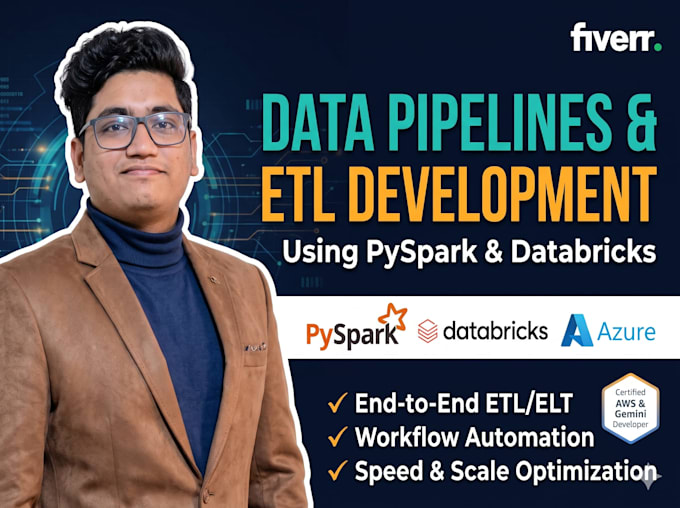
Are you looking for robust, high-performance data pipelines built for scale?
I specialize in building, optimizing, and automating end-to-end ETL/ELT pipelines using PySpark, Databricks, and modern cloud data architectures. Whether you need to ingest messy raw files, transform complex datasets, or migrate structured data, I deliver reliable, production-ready solutions.
Services Offered:
1. Custom ETL/ELT pipeline design and workflow automation
2. Large-scale data processing and transformation with PySpark & Databricks
3. SQL query tuning, data validation, and deduplication
4. Integration with cloud storage (Azure Data Lake, Synapse, Databricks Lakehouse)
5. API integration, testing, and automated ingestion workflows
6. End-to-end data migration and governance support
Tech Stack:
Databricks, Apache Spark / PySpark, Azure Synapse, ADLS, Python, SQL, REST APIs / Postman.
Why Work With Me?
Hands-on enterprise data engineering & data stewardship experience
Clean, modular, well-documented code
Timely delivery with clear communication
Please message me with your project requirements and sample data before placing an order so we can pick the best scope!