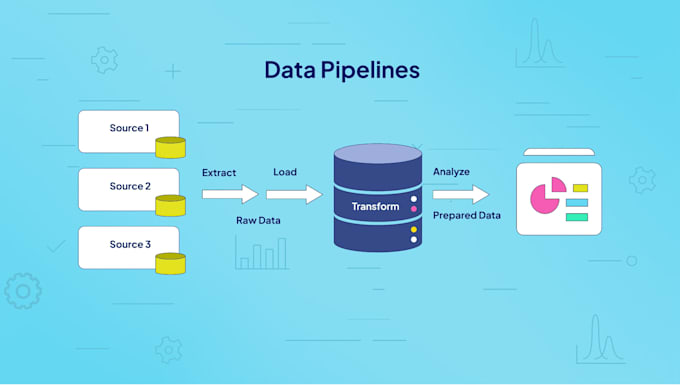
I am a professional Data Engineer with 3+ years of experience designing and optimizing high-scale data platforms processing 400+ TB daily. Whether you need end-to-end ETL pipelines, real-time streaming, or fast analytical databases, I build reliable, cost-efficient data systems.
What I Can Do For You:
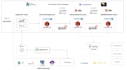
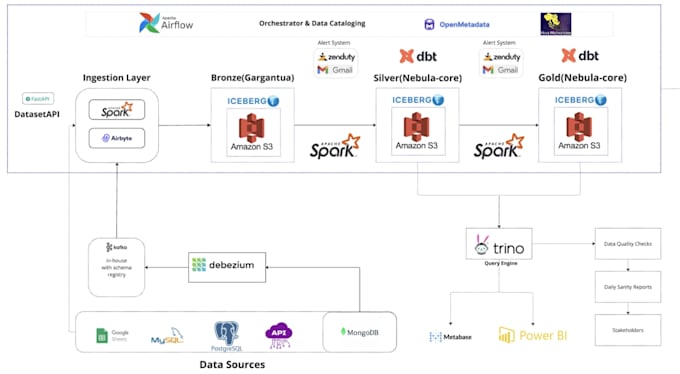
- ETL & ELT Pipelines: Design and automate scalable batch pipelines using Python, SQL, Apache Spark (PySpark), and Airflow.
- Modern Lakehouse & Warehouse: Architecture and setup with Apache Iceberg, Trino, ClickHouse, Redshift, and PostgreSQL.
- Transformations & Modeling: Robust gold/silver layers with dbt, modular data modeling, and testing.
- Real-Time CDC & Streaming: Kafka integration, Debezium CDC, and ClickHouse live ingest.
- Performance Tuning: Optimize complex SQL queries, resolve bottlenecks, and slash infrastructure costs.
Why Work With Me?
- Production-tested engineering standards
- Scalable, clean, and fully documented code
- Clear communication and on-time delivery
Please message me before placing an order to discuss your architecture and requirements!