Kategorien durchsuchen
Entdecken
Fiverr Pro
Deutsch
$
USD

I build RAG ready knowledge bases from your texts
Kompetenzen
Meine Dienstleistungen

Knowledge Base Architect & Data Engineer
Fiverr • Selbstständig
Jan 2026 - Present • 9 mos
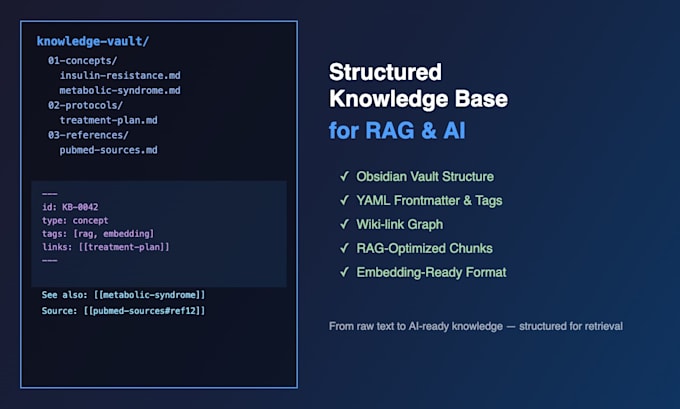
I build structured, RAG-ready knowledge bases in Obsidian from unstructured source materials — medical textbooks, video lectures, web databases, and clinical courses. Key project: TCM Knowledge Base (4,400+ notes) • Processed 25 expert sources across Traditional Chinese Medicine: acupuncture, herbal medicine, diagnostics, dietary therapy, aromatherapy • OCR extraction from scanned PDFs (3,000+ pages) using PDFgear and pdftotext • Built custom Python parsers for web databases (eledia.ru, kiberis.ru, TCMwiki), extracting 1,280+ acupuncture points and 245 treatment protocols • Structured 303 herbal monographs with molecular cross-references from LOTUS (659K compound-organism pairs), PharmGKB, and CPIC databases • Created 99 food-as-medicine entries with full TCM classification • Transcribed video lectures using Whisper (pywhispercpp) for speech-to-text processing Technical approach: • Consistent YAML frontmatter on every note for automated parsing and vector embedding • Wiki-link knowledge graph connecting herbs, acupoints, diseases, and treatment schemes • Standardized taxonomy: 14 meridian codes, functional categories, body-region tags • Semantic chunking — one concept per note, optimal for RAG retrieval Tools: Obsidian, Claude AI, Python, PDFgear, Whisper, LOTUS/PharmGKB/CPIC molecular databases GitHub portfolio: github.com/Smeilz/tcm-knowledge-base
