Kategorien durchsuchen
Deutsch
$
USD
Deine KI mit Fiverr verbinden
Computer Vision and AR Engineer, PhD Researcher
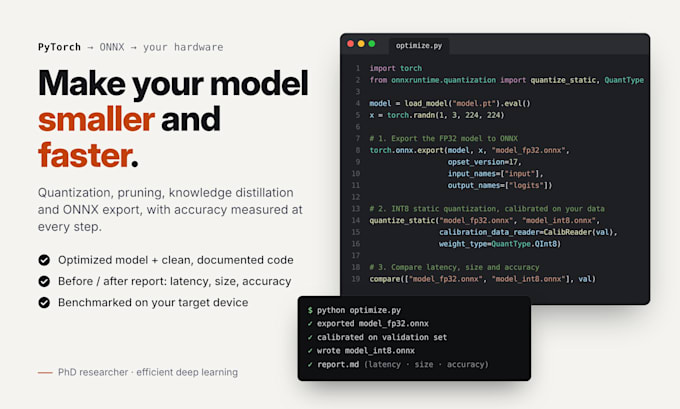
Is your PyTorch model too slow, too large or too expensive to run in production? I am a PhD researcher in computer vision with peer-reviewed publications on model compression and knowledge distillation. I will make your model smaller and faster while keeping accuracy under control.
What I can do:
What you get:
Please message me before ordering with your model architecture, framework version, target hardware (GPU, CPU, Jetson, mobile) and accuracy budget, so I can confirm the right package.
Programmiersprache:
Python
•
Colab
Tools:
Jupyter-Notizbuch
•
opencv
•
PyTorch
Frameworks:
keras
•
PyTorch
Will optimization reduce my model's accuracy?
Some techniques can cost a small amount of accuracy. We agree on an accuracy budget before I start, I measure every step and you get before/after numbers, so there are no surprises.
Which models and frameworks do you support?
Mainly PyTorch vision models: classification, detection, segmentation and similar tasks. TensorFlow/Keras models can often be handled through ONNX. If your model is unusual, message me first and I will tell you honestly whether I can help.
Do you need my training data?
Quantization and ONNX export only need a small calibration/validation set. Distillation and fine-tuning need access to training data. Your model, code and data stay confidential and are never reused.
Which hardware do you test on?
I benchmark on NVIDIA RTX GPUs (TensorRT, ONNX Runtime GPU), x86 CPUs, Apple Silicon Macs and Android phones. For Jetson or other edge boards I deliver the exported model plus a benchmark script you can run, or I test with access you provide.
What exactly do I receive?
The optimized model files (for example ONNX or a TensorRT engine), clean Python code that reproduces every step, and a short report with before/after latency, model size and accuracy.
