Kategorien durchsuchen
Entdecken
Fiverr Pro
Deutsch
$
USD
Director, Data Analytics
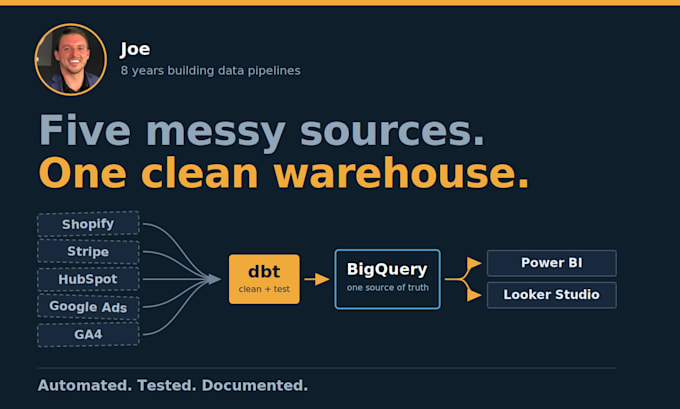
Most data problems are not analysis problems. They are plumbing problems. The numbers live in five tools, three of them disagree, and someone on your team rebuilds the same report by hand every Monday.
I build the pipeline that makes that stop.
What I do:
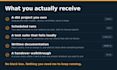
Move your data from its sources into BigQuery on an automated schedule. Model it in dbt so it is clean, tested, and documented. Hand it back structured so your reports pull from one source instead of five.
Typical sources: Shopify, Stripe, HubSpot, Salesforce, Google Ads, Facebook Ads, GA4, Postgres, MySQL, Google Sheets.
Who this is for:
Teams who already have data and cannot trust it. If you are exporting CSVs to stitch reports together, this is the fix.
Why me:
Ten years in analytics, most of it agency-side running pipelines for CPG, financial services, and retail media clients. I have built this for companies where the reporting was going to a CMO, so it had to be right.
You get working code, documentation, and a walkthrough. No black box you have to pay me to maintain.
Message me with what tools you are using and I will tell you whether this is the right fit before you order.
Do I need a BigQuery account already?
No. If you do not have one, I will walk you through creating the project during onboarding. You own the account and the billing, not me. Google's free tier covers most small to mid-size workloads.
What does this cost to run after you are done?
The pipeline itself is yours with no ongoing fee to me. You pay Google for BigQuery storage and queries, which for most small businesses is a few dollars a month. If you use a paid connector tool like Fivetran, that has its own pricing based on row volume. I will tell you the expected cost before we
What access do you need from me?
Read access to your data sources and admin on the BigQuery project. I never need your passwords. Everything runs through proper API credentials or service accounts that you can revoke at any time.
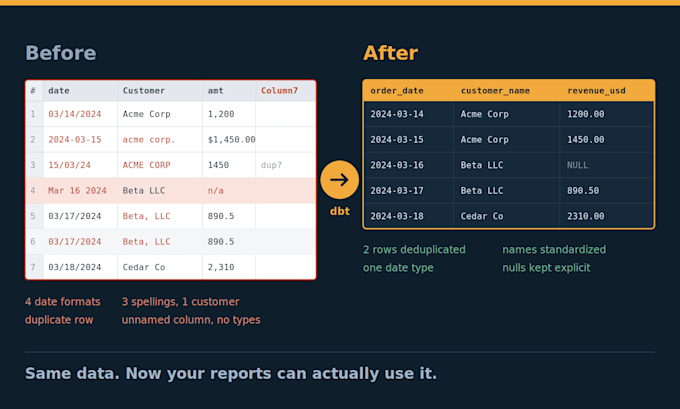
My data is messy. Is that a problem?
That is the job. Duplicate records, inconsistent naming, mismatched date formats, and columns that mean different things in different systems are normal. Cleaning that up is what the dbt modeling layer is for.
Can you connect a source that is not in your list?
Usually yes. If the tool has an API or exports to a database, it can be connected. Message me before ordering and I will confirm.
What happens if the pipeline breaks later?
You get documentation explaining how it works and how to fix common issues. I am also available for ongoing support as a separate arrangement if you want it. Nothing is locked behind me.
Do you build the dashboards too?
Not in this gig. This gets your data clean and structured so your existing tools work properly. If you need dashboards built on top of it, message me and we can scope that separately.
Why not just use a no-code tool?
For one simple source, a no-code tool may be enough. This is for when you have several sources that need to be joined, deduplicated, and reconciled against each other, which is where those tools fall apart.