Kategorien durchsuchen
Entdecken
Fiverr Pro
Deutsch
$
USD

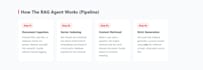

Are you ready to bring the power of LLMs and custom AI to your business?
I am a software developer specializing in Artificial Intelligence integrations, RAG (Retrieval-Augmented Generation) architectures, and modern web applications. Whether you need a simple backend API or a complete custom chat application that securely queries your own documents, I can build a robust solution tailored to your needs.
What I Offer:
Custom RAG Systems: Chat with your PDFs, databases, or company docs using local or cloud-based LLMs.
Backend & APIs: Fast, secure, and scalable endpoints built with Python and FastAPI, fully optimized for token streaming.
Full-Stack Solutions: Seamless and responsive frontend interfaces developed with React and TypeScript.
Local AI Deployment: Setup of privacy-first local models using Ollama and vector databases like Qdrant.
My Tech Stack:
Python, FastAPI, React, TypeScript, JavaScript, SQL, Ollama, Qdrant, Hugging Face.
Please send me a message before placing an order! I want to understand your specific requirements to ensure we choose the best architectural approach for your project.
AI Backend Engineer RAG Vector Search
Sprachen
Why should I choose a custom AI architecture over generic commercial platforms?
custom build gives you complete ownership and control. Instead of forcing your data into a rigid framework, we design a tailored Retrieval-Augmented Generation (RAG) pipeline that adapts exactly to your business logic while preventing vendor lock-in.
How does the system read and search through my specific company documents?
We integrate modern vector databases, such as Qdrant, to process your PDFs, databases, or company text. This allows the system to instantly find the most relevant context based on semantic meaning, feeding the exact right information to the AI.
How do you prevent the AI from inventing facts (hallucinating)?
The architecture uses a strict RAG approach. The model is constrained to answer only using the context retrieved from your verified documents. We separate strict logic from language generation to ensure your data remains 100% accurate.
Can this handle highly sensitive company data?
Absolutely. For maximum security, I can set up privacy-first local AI deployments using Ollama. This means the Large Language Models (LLMs) and your data run entirely on your own infrastructure, ensuring nothing is ever sent to third-party APIs.
What technologies do you use for the application?
The backend is powered by Python and FastAPI, which guarantees fast, scalable endpoints optimized for AI token streaming. If you need a full-stack solution, the frontend is built with responsive React and TypeScript.
How do we start a new project?
Please send me a direct message before placing an order. We will discuss your specific requirements, data types, and use case to ensure we select the most effective architectural approach for your needs.


