Kategorien durchsuchen
Deutsch
$
USD
Verbinden Sie sich mit Ihrer KI
Set up private local AI or tune your OWN GPU workstation
Kompetenzen
Meine Dienstleistungen
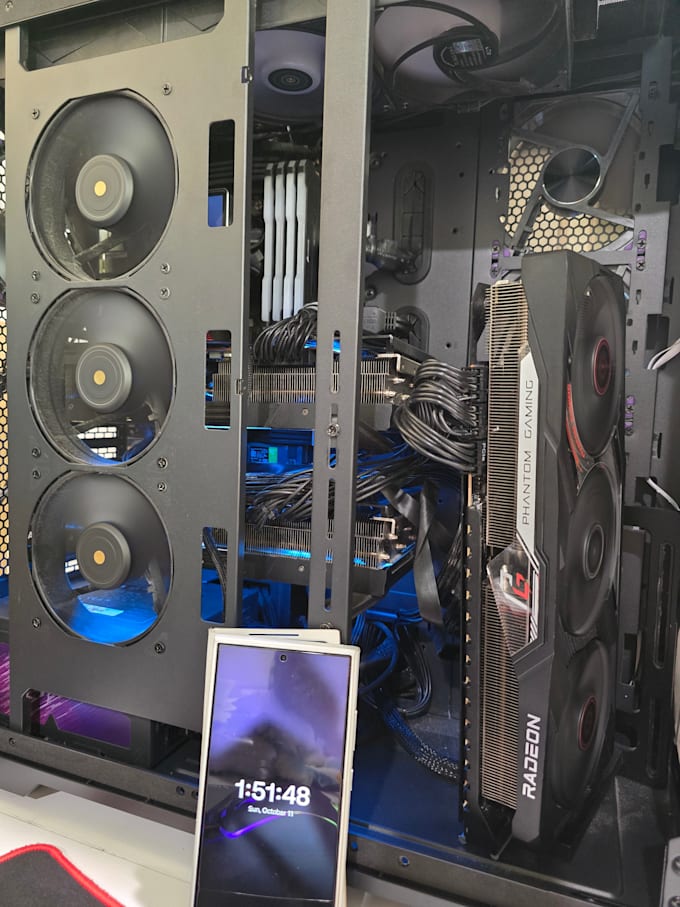

Private Local AI Deployment & Hardware-Optimized Workflows
Self Employed
Jan 2026 - Present • 10 mos
Tired of unpredictable cloud API costs, data privacy concerns, and driver conflicts? I set up, tune, and harden private, offline AI workstations and servers that extract every ounce of performance from your existing hardware. Whether you are running consumer GPUs or dedicated multi-GPU workstations, I eliminate installation headaches, resolve driver/runtime mismatches, and deliver an intuitive, browser-accessible interface ready for production work on day one. Core Capabilities Local LLM Engines & APIs: Turnkey deployment of Ollama, vLLM, SGLang, and llama.cpp with OpenAI-compatible endpoints. Interfaces & Frontends: Clean setups of Open WebUI, LibreChat, and custom local dashboards with user authentication and document management (RAG). Creative AI Pipelines: Stable Diffusion and Flux installations via ComfyUI or Automatic1111, configured with custom nodes, LoRAs, and control nets. Agent Frameworks & Automation: Orchestration setups for autonomous agents, tool-calling pipelines, and local embedding models. Hardware & Runtime Optimization: Driver configuration, VRAM allocation tuning, context window optimization, and quantization matching (GGUF, AWQ, EXL2) across Linux and Windows environments. Why Clients Trust My Work Total Data Privacy: Your machine, your data. I configure your tools strictly for offline/local execution with zero unauthorized telemetry or external dependencies. Stress-Tested Reliability: I do not simply run an installer script and log off. Every deployment is benchmarked under load to confirm thermal stability, VRAM headroom, and token throughput. Structured Handoff & Documentation: You receive clear, step-by-step documentation on how to update models, manage storage, and restart services without breaking dependencies. Transparent Communication: If your hardware cannot realistically run a specific model or quantization level, I tell you up front and recommend the optimal compromise.
