I will optimize llm infrastructure, deploy vllm, and slash GPU cloud costs

B
bipro515
B
bipro515
Biprojit Adhika
Einige Informationen werden in englischer Sprache angezeigt.

Über diesen Service

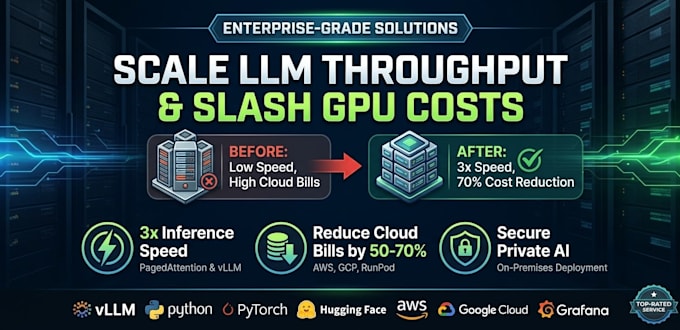
Are your monthly AWS, GCP, or RunPod GPU bills skyrocketing? Is your LLM throughput bottlenecked by latency?

​I am an LLM Infrastructure Specialist & Private AI Architect. I help AI companies and engineering teams optimize open-source LLM deployments (Llama 3, Mistral, DeepSeek) to maximize request throughput and dramatically slash cloud infrastructure costs.

​ What I Can Do For You:

  • ​vLLM & PagedAttention Deployment: Scale request throughput by 3x-4x compared to vanilla Hugging Face pipelines.
  • ​Model Quantization (AWQ / GPTQ / FP8): Reduce VRAM usage by up to 60-70% with negligible loss in accuracy.
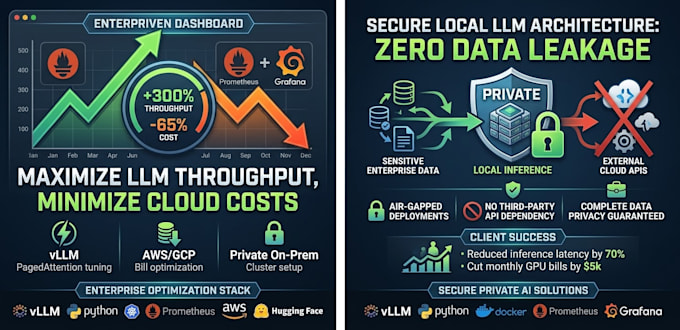
  • ​GPU Cloud Cost Optimization: Slash monthly GPU spending on AWS/GCP/RunPod while serving more concurrent users.
  • ​Private AI & On-Premises Migration: Deploy secure, air-gapped local LLMs on your infrastructure for complete data privacy.
  • ​Monitoring & Analytics: Setup Prometheus + Grafana dashboards to track latency, token generation speed (tokens/sec), and GPU utilization in real time.

​️ Why Choose Me?

  • ​High ROI: My infrastructure optimization setups pay for themselves within the first month of server cloud savings.
  • ​Production-Ready Delivery: Clean Dockerized environments and automate

Lerne Biprojit Adhika kennen

Biprojit Adhika

Principal Architect LLM Infrastructure Private AI

  • AusBangladesch
  • Mitglied seitOkt. 2026
  • Sprachen

    Englisch
I am a high-impact Principal AI Infrastructure Architect specializing in LLM performance optimization and zero-data-leakage Private AI architecture. I have a proven track record in slashing enterprise hosting costs by 50%–80% using advanced quantization and high-speed inference engines. I expertize in orchestrating resilient Linux GPU clusters and localized vector search infrastructure.

Mein Portfolio