Kategorien durchsuchen
Entdecken
Fiverr Pro
Deutsch
$
USD

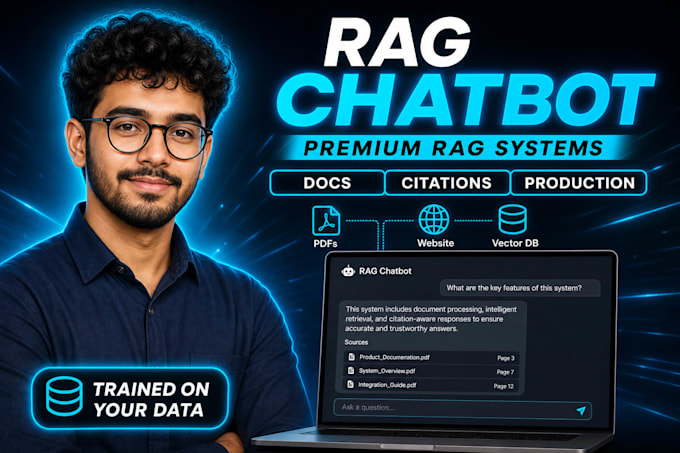

Your docs, not generic chat.
I build RAG chatbots that answer from YOUR PDFs, websites, or databases - with citations. Chunking, embeddings, a vector store, and a grounded chat UI. You get source code, a runnable app, and a short handoff.
What you get:
Stack: Python, FastAPI or Next.js, LangChain or LlamaIndex, OpenAI / Anthropic / local LLMs, Docker.
Process: you send sample docs + real questions, I ship an index + chat loop, we iterate on wrong/missing answers, then handoff.
To start: 5-20 sample files and 10 real questions. Message me if you need Slack, SSO, or a specific vector DB.
AI Engineer, RAG, ML and Agents
Sprachen
Will the bot invent answers not in my documents?
RAG still uses an LLM, so it can drift. I ground answers in retrieved chunks, show citations, and prompt it to say it does not know when retrieval is weak. Premium adds an eval set so we measure that.
Can you keep my data off OpenAI?
Yes - Azure, a VPC endpoint, or a local model (Ollama / vLLM). Say this up front. I will not send your files to a public API unless you approve it.
What if my PDFs are scanned or messy?
Scanned PDFs need OCR. Tables and multi-column layouts need extra parsing. Tell me in the order; OCR or heavy cleanup may be an extra if volume is large.
Do I own the code?
Yes. You get the project files. Third-party APIs stay on your accounts and billing. I do not claim your data or lock you into a hosted product of mine.
